 Service
Web Scraping & Data Pipelines
Custom scrapers, crawlers and ETL pipelines — scheduled data collection, proxy rotation, JS-rendered sites, change detection and multi-format delivery.
About This Project
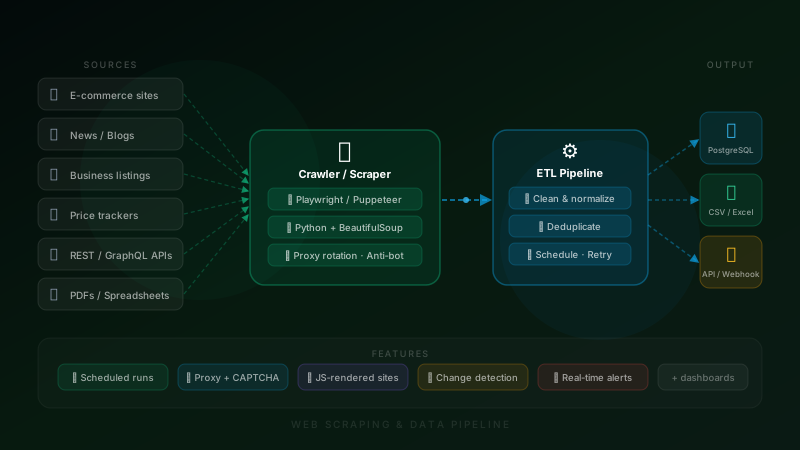
I build custom data collection systems — scrapers, crawlers and ETL pipelines tailored to your specific data source and destination. Every project is different: some sites are static HTML, some require a full browser to render JavaScript, some have aggressive bot protection. I handle all of it.
What I build: targeted scrapers for specific pages or product listings, broad crawlers that traverse entire sites or categories, API integrations that pull data from REST or GraphQL endpoints, document parsers for PDFs and spreadsheets, and ETL pipelines that clean, normalize, deduplicate and load data into your target system.
Technical approaches I use: Playwright and Puppeteer for JavaScript-rendered sites that require a real browser, Python with BeautifulSoup and requests for fast lightweight scraping, rotating proxy pools to avoid IP bans, CAPTCHA solving integrations when needed, scheduled runs via cron or BullMQ, change detection with alerts when monitored data changes, and retry logic with exponential backoff for reliability.
Data delivery options: PostgreSQL or MySQL database, CSV or Excel export, JSON via REST API or webhook push, Google Sheets integration, or any other format your system accepts.
Use cases I have built for: price monitoring across competitor e-commerce sites, lead generation from business directories, real estate listing aggregation, news and content monitoring with keyword alerts, product catalog synchronization between platforms, and financial data collection.